Playlist
Inference Internals(12)
Short videos on how LLMs behave in production. Each one answers one question, such as why the bill grew or why a stream froze, and every video has a written version.
- 1
 7:35#1coming soonOne Line in Your Prompt Can 5x Your LLM BillYour support agent's first invoice is $40. You add the current time, to the second, as the first line of the system prompt. The next invoice is over $200, with the same traffic, the same code and the same model. This video follows that one line to the answer.
- 2
 12:04#2coming soonTTFT, Tokens per Second and Cost: Your LLM Call's 3 NumbersYour run log shows three numbers for one model call: TTFT (time to first token) 2.1 s, 34 tokens per second, and $0.004. This video gives each number a cause, an owner and a knob.
- 3
 4:45#3coming soonWhy Temperature 0 Is Not DeterministicYour CI suite runs your agent at temperature 0 and checks the output text exactly. Ten runs matched, the test shipped, and now it fails at random. Temperature 0 has no random step, so where does the difference come from, and what should the test check?
- 4
 8:17#4coming soonWhy Your LLM Gets Slower at 3pmYour support agent's mean time to first token (TTFT) is 870 ms in the morning and about 1,700 ms at 3pm. The prompt, the code and the API key did not change. This video follows the request into the inference server to find what did change, and which plot shows it.
- 5
 10:08#5coming soonWhy AI Chat Freezes Mid-SentenceYour support agent's dashboard is green, with a median TTFT of 600 ms, but users see answers stop mid-sentence for almost a second. A batching simulator shows a 764 ms gap between two tokens of one answer. This video finds what stops one answer while every metric says healthy, fixes it, and names the metric that would have caught it.
- 6
 7:16#6coming soonStrict JSON Mode Cost Us 9 Accuracy PointsYou turn on strict JSON mode for a ticket classifier. Every answer now parses, and accuracy falls 9 points the same day. This video finds who took the points, and what to change.
- 7
 7:10#7coming soonWhy Long AI Agent Runs Die with a 400Six hours into an agent run, one tool result is far larger than any before it, and the provider answers 400: the prompt no longer fits the context window. This video answers what must survive a compaction, and what to do when the 400 arrives.
- 8
 10:33#8coming soonPrompt Caching Can Cost You 25% MoreYou turn on prompt caching for an agent that sends the same 12,000-token system prompt on every call. The input bill goes up by about 25%, and every call returned 200 OK. This video explains why, and which one number would have told you.
- 9
 11:56#9coming soonIs Your LLM Router a Coin Flip?Your team tests two cascades: each tries a cheap model first and passes unsure queries to a strong model. Both dashboards show 85% accuracy at 69% of the strong model's cost, and one of them picks the queries it passes on with a coin flip. This video builds the test that tells them apart, and picks the signal worth building.
- 10
 9:16#10coming soonThe Cache Bug No Dashboard Caught for 4 MonthsA release adds a request ID, for tracing, to the first line of your agent's 18,000-token cached system prompt. Every response still returns 200 with the same token count, every dashboard stays green, and for four months every request pays full price for the prompt. This video catches it within two requests and puts a hard ceiling on the spend.
- 11
 11:21#11coming soonWhy My First $3.49 GPU Hour Served Zero TokensManagement gives you one rented GPU hour and $5 to $10, to test if serving a model yourself costs less than a hosted API. The hour on an H100 ends without an error, and the server has served zero tokens. This video follows that hour, and the next one, to one honest number.
- 12
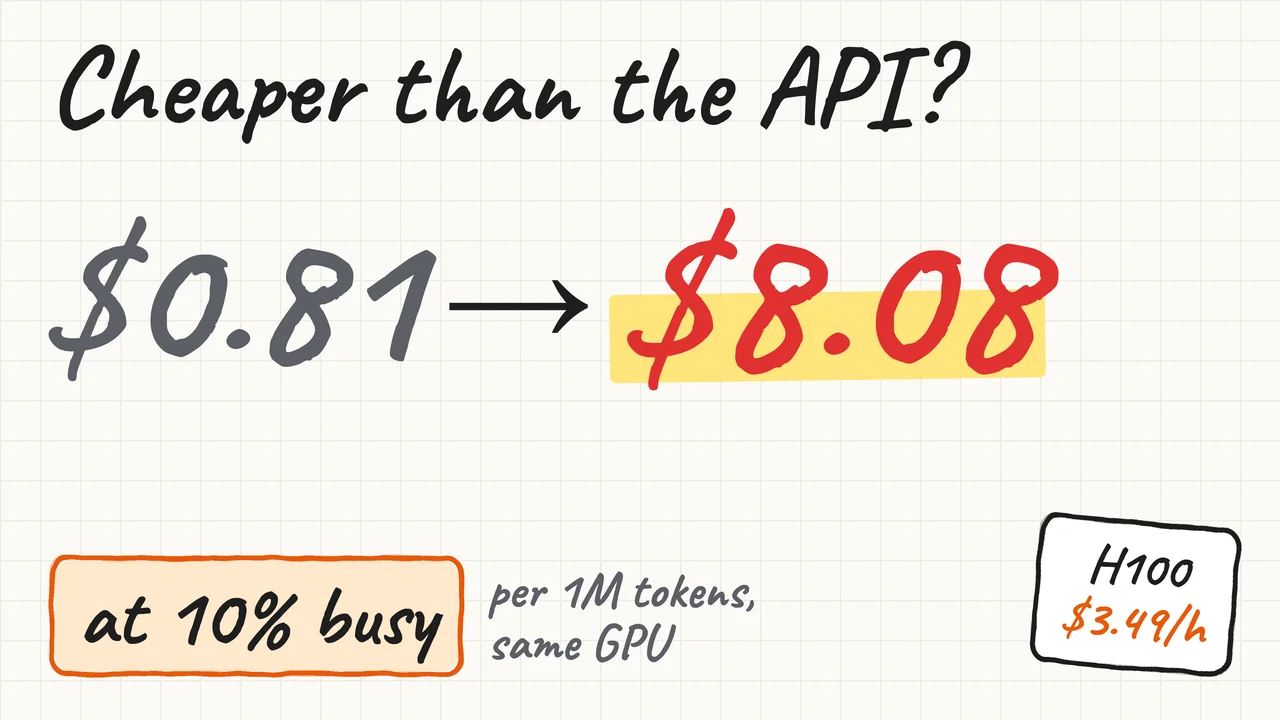 13:01#12coming soonIs Self-Hosting Your LLM Cheaper Than the API?A rented H100 at $3.49 an hour serves 1,200 output tokens per second at full load. In a meeting, someone divides: $3.49 by 4.32 million tokens an hour is about $0.81 per million tokens, so self-hosting looks twice as cheap as a $1.60 API. A teammate adds a 4-bit checkpoint with about 99% recovery. This video checks both claims.